
Explore the conversation.
AI for Nature at Large Scale and High Resolution
AI can help fill biodiversity knowledge shortfalls only if biological knowledge is built into the models and the data infrastructure is FAIR for AI and returns value to primary data collectors, because 'there is no AI without data'.
Tanya Berger-Wolf ↗
AI-assisted digitisation of printed identification keys: from book to structured data in minutes
An agentic LLM pipeline can turn printed keys and descriptions into a structured draft identification key for tens of dollars, shifting experts from transcribers to reviewers.
Wouter Koch ↗
Future interfaces for BHL
Modern AI tools make new BHL interfaces feasible now (better OCR, image and map search, chatbots); the community must decide which are worth building.
Roderic Page ↗
SYM08A closing discussion: sustaining and connecting the BHL ecosystem
Focusing on core functions made GBIF and BHL successful; sustaining the connected ecosystem now requires clear value statements and machine interfaces such as MCP servers.
Nicole Kearney ↗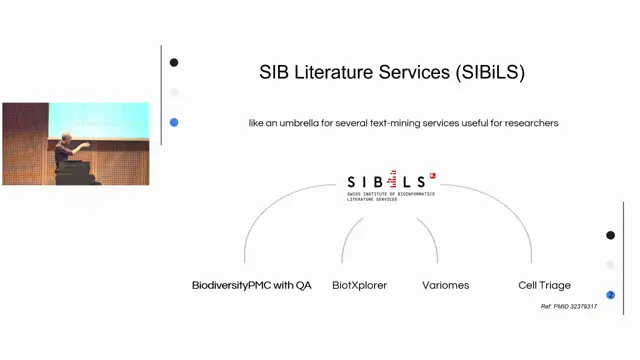
How Literature Services can Support & Benefit from Biodiversity Publication and Data Standards?
Standards-based concept annotation of biodiversity literature enables focused, evidence-grounded question answering that is more precise than general chatbots.
Patrick Ruch ↗
Literature triage to support Island Biodiversity Monitoring
Classifier-based literature triage matches human curators at a fraction of LLM cost and is worth investing in for recurring curation tasks.
Patrick Ruch ↗
Contained Agentic Workflow for Literature Analysis and Data Extraction in Museum Collections
Contained, local agentic RAG over a literature corpus is feasible on a laptop or shared edge machine, avoiding the security worries of cloud agents in museums.
Steen Dupont ↗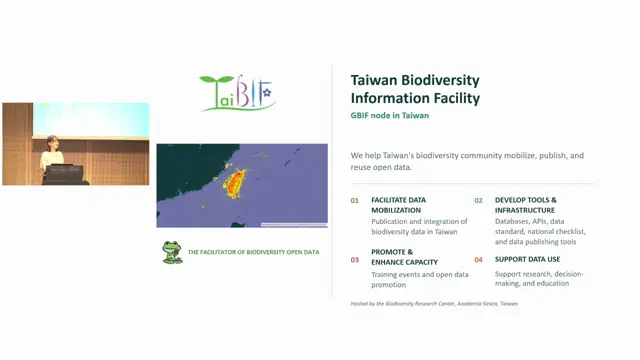
Empowering and Expanding Communities from Knowledge to Best Practices in Data Mobilization: The TaiBIF Collaborator Training System
A tiered, role-based certification pathway linked to paid assignments lets a small GBIF node multiply its support capacity.
Melissa Chin-Yi Lu ↗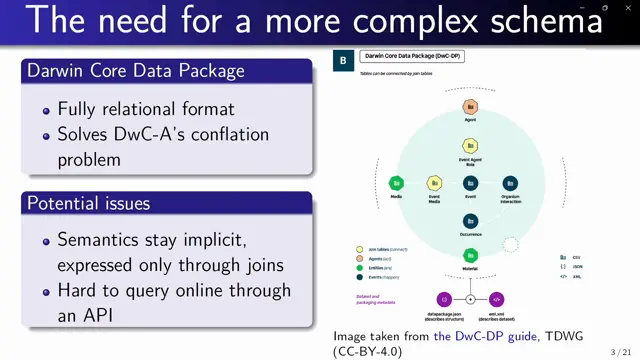
Enabling machine-readable access to biodiversity data through federated semantic querying
Distribute the data, not the infrastructure: cloud Parquet plus OBDA query rewriting gives a virtual Darwin Core knowledge graph without duplicating data into RDF.
El-Amine Mimouni ↗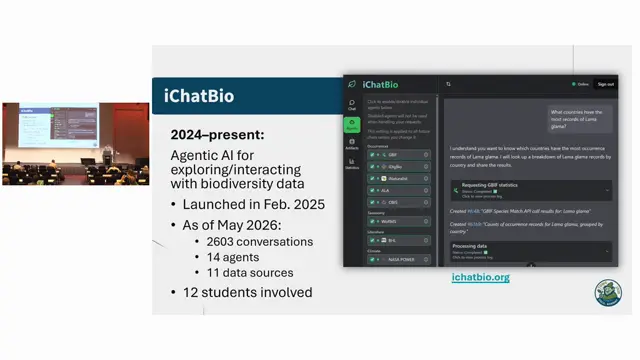
Integrating Many Data Sources in iChatBio Enables Emergent Scientific Use Cases
iChatBio's specialised agents let a conversational interface combine many biodiversity data sources, with traceable, non-hallucinated data artefacts.
Michael Elliott ↗
Reliable LLM-assisted curation of ecological survey data: a deployed agent bridging field collection and data curation
An LLM agent that proposes findings for curator approval, with confirmed patterns turned into deterministic rules, catches plausibility errors that schema validation misses.
Andrew Tokmakoff ↗