
Across rooms and sessions
Explore the conversation.
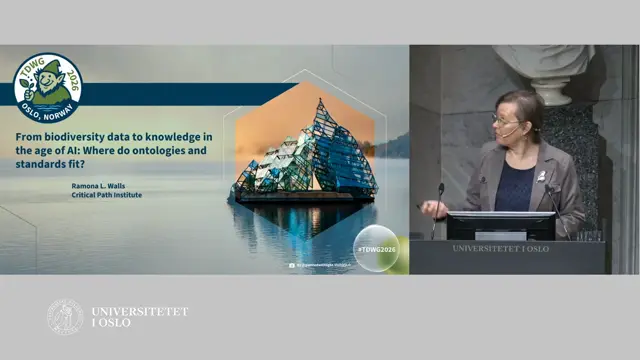
talk · Monday 21 September · Aula
From biodiversity data to knowledge in the age of AI: where do ontologies and standards fit?
AI can generate data and candidate knowledge, but only standards, ontologies, provenance and governance let data become trusted evidence and therefore knowledge, which is why TDWG matters more than ever.
Ramona Walls ↗
talk · Tuesday 22 September · SAL A
Introduction to the AI for Biodiversity Data session: what machine learning and LLMs actually do
LLMs are word predictors with no notion of truth, so their outputs, including hallucinations, cannot be objectively scored from the text alone.
David Williamson ↗
discussion · Thursday 24 September · SAL B
Post-BioDT lessons and next-generation biodiversity digital twins
BioDT delivered pilots and, above all, mutual understanding between modellers and data people; the next generation must find real users and real conservation impact rather than chase the digital twin label.
Claus Weiland, Dimitri, Sharif Islam ↗
discussion · Friday 25 September · SAL B
Discussion: designing institutional biodiversity knowledge and data science centres
Interoperable institutional knowledge spaces depend less on technology than on people, shared storage and semantics, incentives and governance.
Unidentified session chair, Lars Vogt, Tarek Al Mustafa ↗